diff --git a/contributing/DOCS.md b/contributing/DOCS.md
index aa07d9673..5cc799a59 100644
--- a/contributing/DOCS.md
+++ b/contributing/DOCS.md
@@ -174,6 +174,12 @@ toward a dedicated local bundle or custom Swagger UI layout instead of adding mo
That bundle can still use the single generated `openapi.json` and filter by tag on the client, so
we should not reintroduce per-tag OpenAPI files unless there is a concrete reason.
+#### 5. Unlisted blog posts
+
+A blog post with `unlisted: true` in its frontmatter is built and reachable by its URL, but
+`on_page_context` drops it from the blog index and category pages. It still appears in search
+and `sitemap.xml`.
+
### File structure
```
diff --git a/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md b/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md
index dd0c9cb81..7614b4d28 100644
--- a/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md
+++ b/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md
@@ -1,8 +1,9 @@
---
title: "Serve GLM-5.3 Coding Agents Faster and Cheaper on GB200 NVL72"
-date: 2026-11-10
-description: "Optimized with dstack presets, 14 GB200 NVL72 nodes serve 48 GLM-5.3 coding agents as fast as the three fastest OpenRouter endpoints, with lower p50 TTFT, and self-hosting them costs under a third of buying the same tokens."
+date: 2026-11-13
+description: "Optimized with dstack presets, 14 GB200 NVL72 nodes serve 48 GLM-5.3 coding agents as fast as the three fastest OpenRouter endpoints, with lower p50 TTFT, and self-hosting them costs less than buying the same tokens."
slug: glm53-gb200-nvl72-coding-agents
+unlisted: true
image: https://dstack.ai/static-assets/static-assets/images/dstack-glm-53-gb200-nvl72-crusoe.png
categories:
- Benchmarks
@@ -10,7 +11,7 @@ categories:
# Serve GLM-5.3 Coding Agents Faster and Cheaper on GB200 NVL72
-With `dstack` [presets](../../docs/concepts/presets.md), the preset agent optimized a GB200 NVL72 fleet to serve GLM-5.3 coding agents as fast as the three fastest endpoints on OpenRouter, with lower p50 TTFT. Self-hosting them this way costs under a third of buying the same tokens from those endpoints. By a coding agent we mean one session of a tool like Claude Code: a multi-turn conversation that resends its whole context, about 135k tokens, on every request and spawns subagents along the way.
+With `dstack` [presets](../../docs/concepts/presets.md), the preset agent optimized a GB200 NVL72 fleet to serve GLM-5.3 coding agents as fast as the three fastest endpoints on OpenRouter, with lower p50 TTFT. Self-hosting them this way costs less than buying the same tokens from those endpoints. By a coding agent we mean one session of a tool like Claude Code: a multi-turn conversation that resends its whole context, about 135k tokens, on every request and spawns subagents along the way.
@@ -18,7 +19,7 @@ This work was done jointly with [Crusoe](https://crusoe.ai), who provided the GB
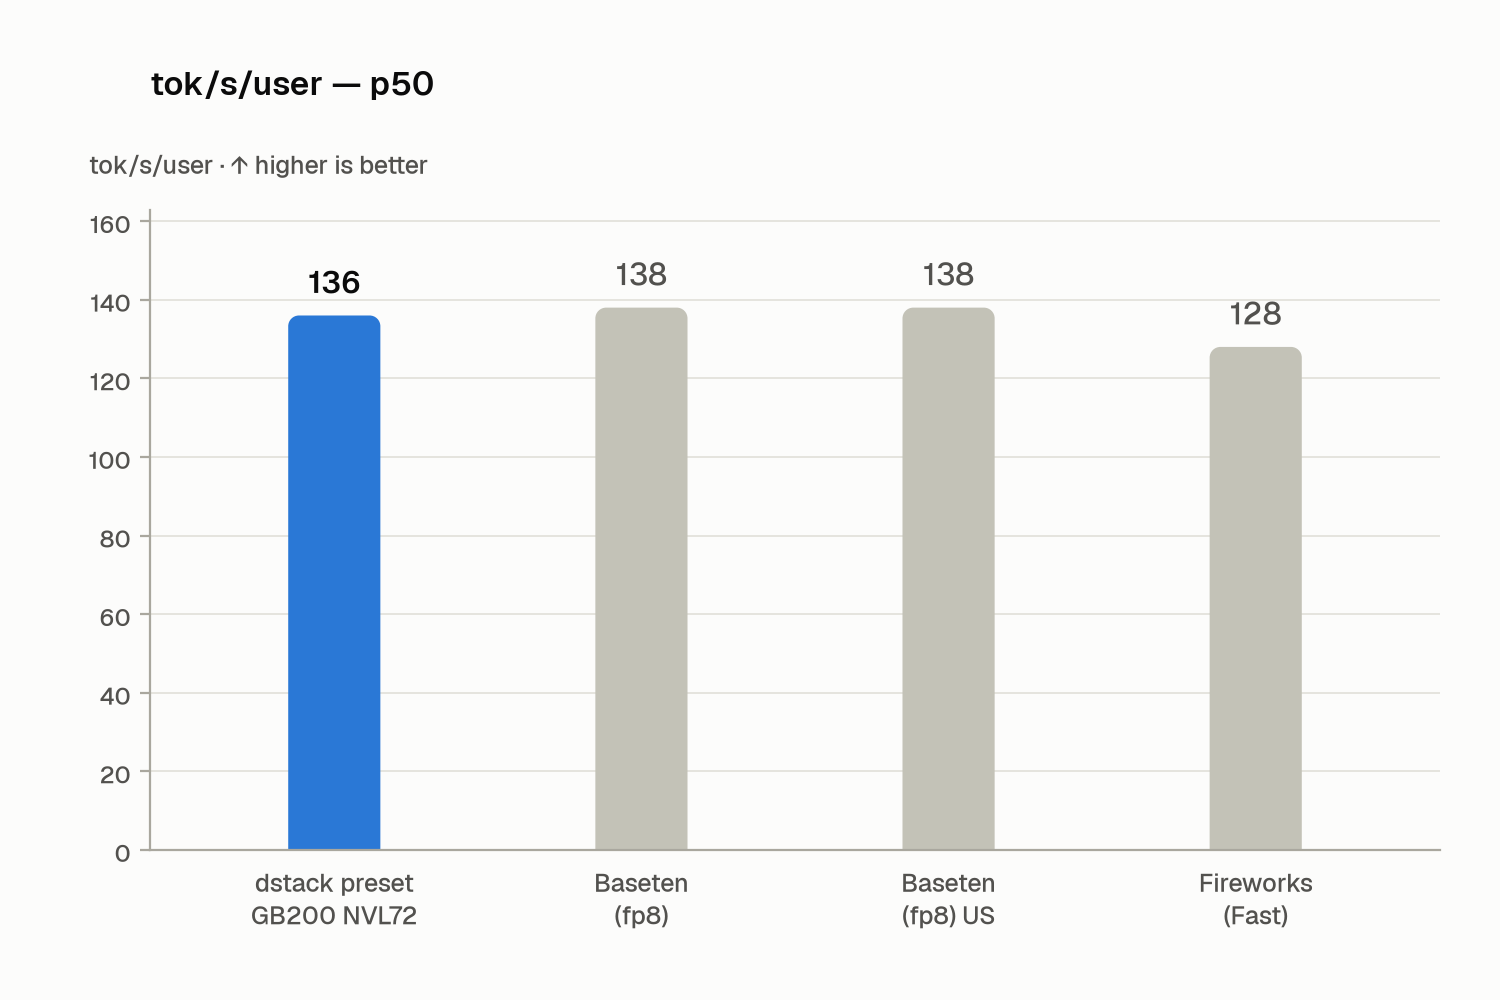
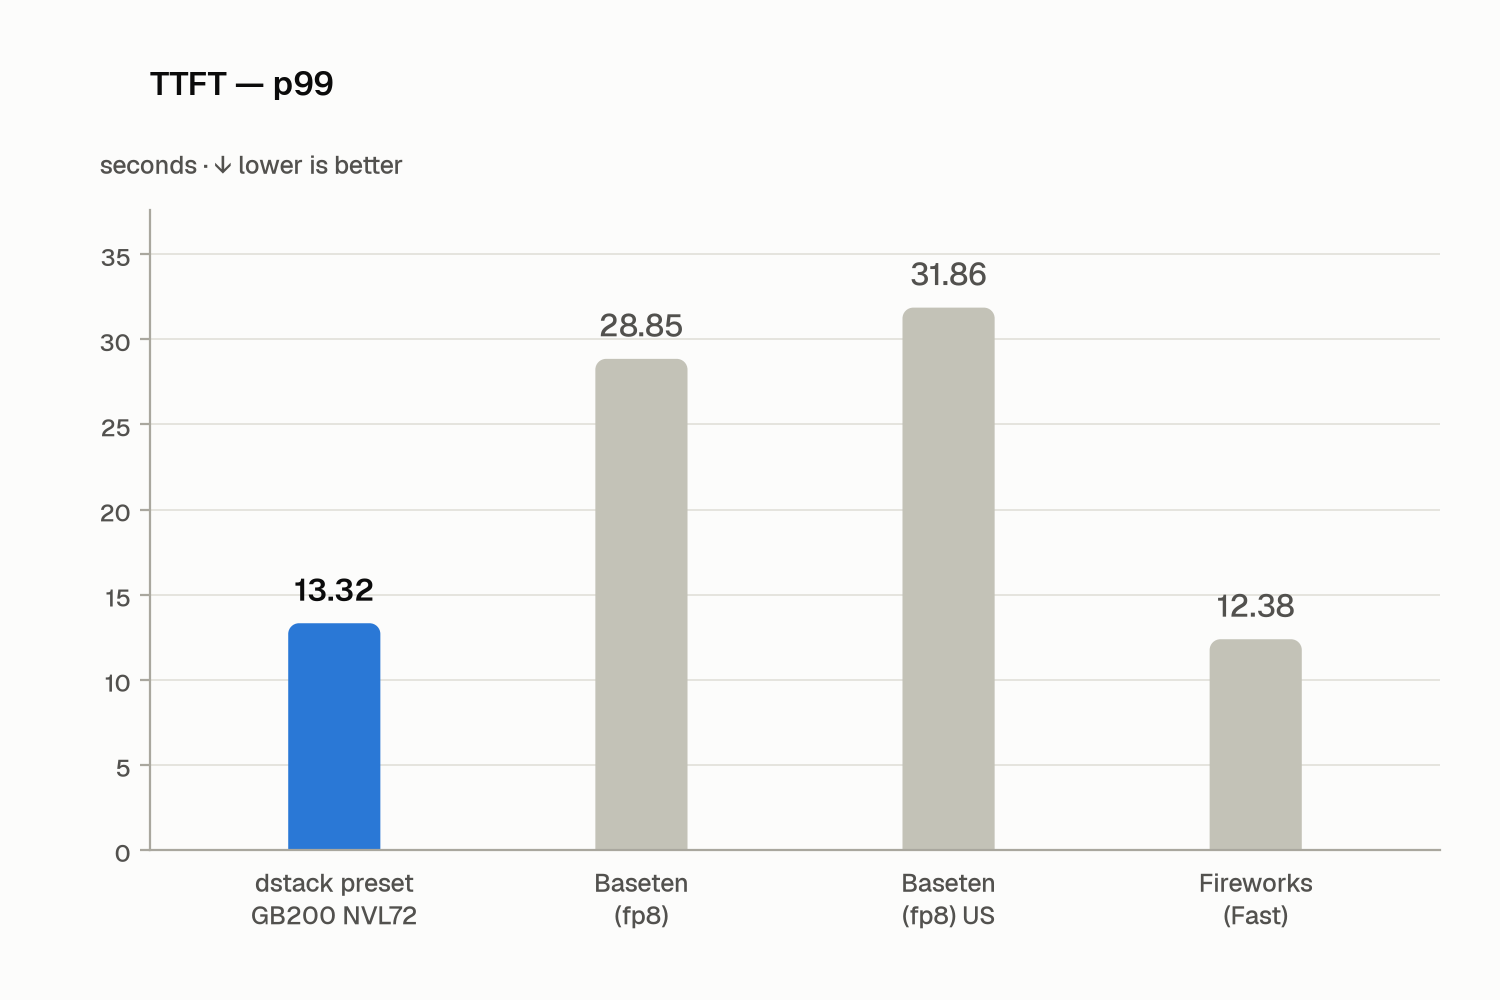
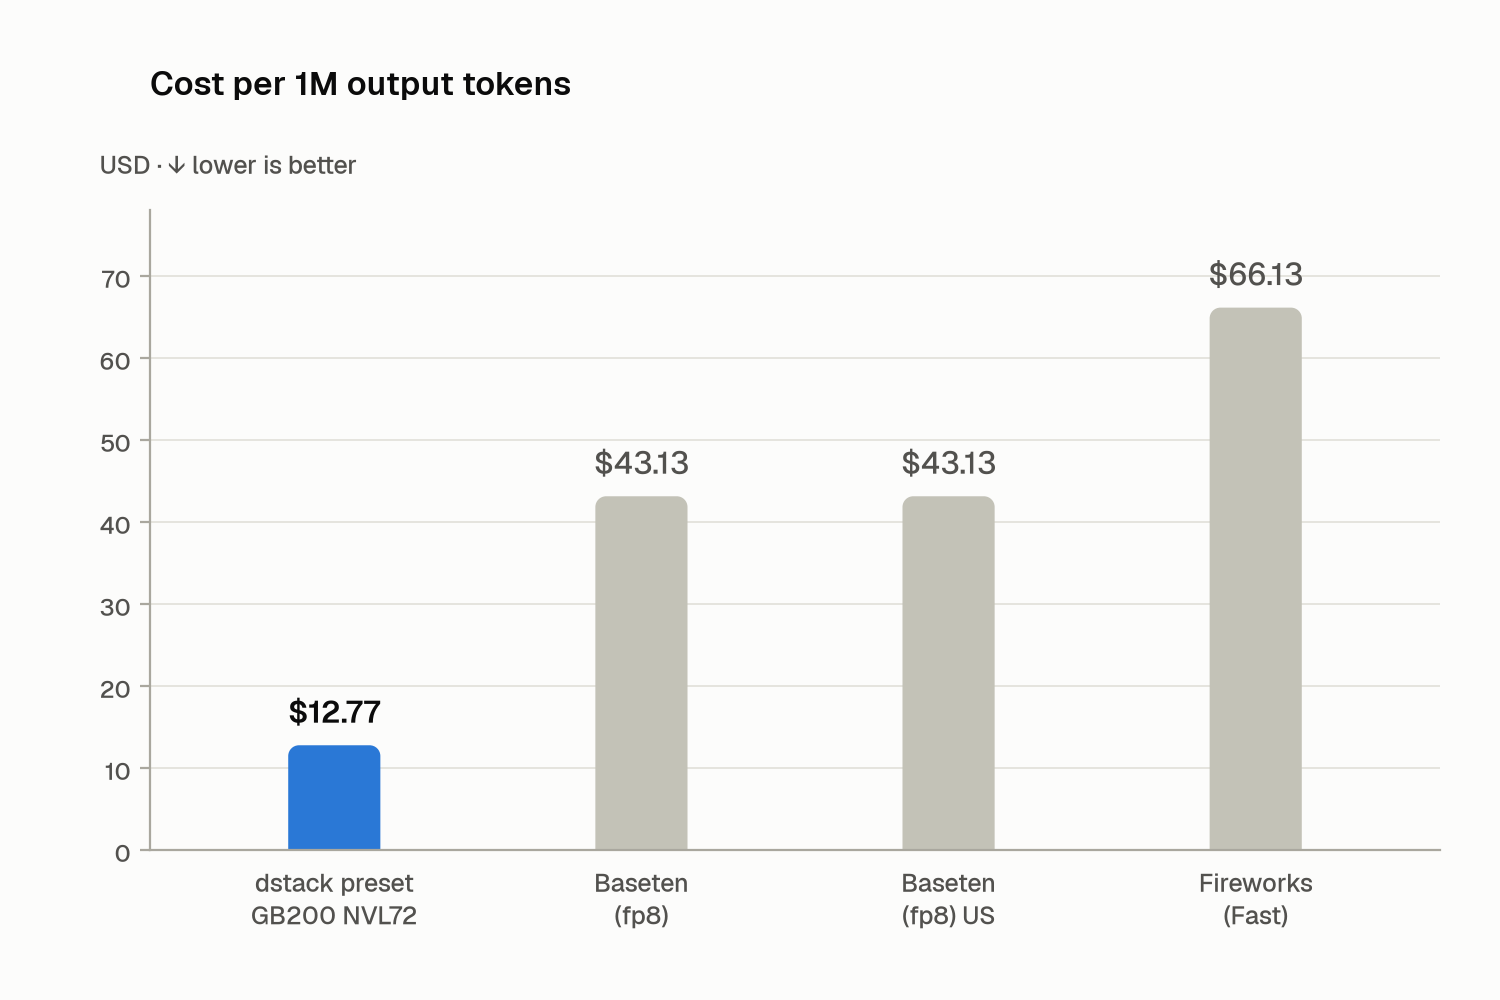
-On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three fastest GLM-5.3 endpoints on OpenRouter, about 3x lower p50 TTFT, and 2x or more higher output speed at p99, where a coding agent's slowest turns are. Serving the same work ourselves costs $12.77 per million output tokens, against $43–66 when buying it from these endpoints.
+On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three fastest GLM-5.3 endpoints on OpenRouter, about 3x lower p50 TTFT, and 2x or more higher output speed at p99, where a coding agent's slowest turns are. Each GPU-hour of the fleet produces 313k output tokens, which would cost $13.51–20.71 to buy from these endpoints.
=== "tok/s/user p50"
@@ -32,10 +33,7 @@ On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three
=== "TTFT p99"
-=== "Cost"
-
-
-> Output speed follows OpenRouter's definition: output tokens per second from sending the request to the end of the response, TTFT included. The self-hosting cost is 56 chips at [$4.00 per chip-hour](https://inferencex.semianalysis.com/chips/gb200-nvl72) divided by the 17.54 million output tokens the fleet produces per hour. The cost of buying applies each endpoint's list prices, including cache-read prices, to our exact token counts. Provider figures are OpenRouter's for 19–26 October.
+> Output speed follows OpenRouter's definition: output tokens per second from sending the request to the end of the response, TTFT included. A GPU-hour's output is the fleet's 17.54 million output tokens per hour divided by its 56 GPUs. The cost of buying applies each endpoint's list prices, including cache-read prices, to our exact token counts. Provider figures are OpenRouter's for 19–26 October.
## Purpose
@@ -107,7 +105,7 @@ We then raised the agent count for each winner. Aggregated, replayed at normal p
### Self-hosting is economically viable
-Optimized for 48 agents, 14 GB200 nodes match the fastest GLM-5.3 endpoints on p50 output speed and beat them on p50 TTFT and on output speed at p99. Self-hosting costs $12.77 per million output tokens, at least 70% less than the $43–66 it costs to buy the same tokens from these endpoints.
+Optimized for 48 agents, 14 GB200 nodes match the fastest GLM-5.3 endpoints on p50 output speed and beat them on p50 TTFT and on output speed at p99. Self-hosting them costs less than buying the same tokens from these endpoints, even on GB200 NVL72 and without patching the engine or writing kernels.
### Cache fit decides aggregated vs PD
@@ -125,7 +123,7 @@ Almost all of the gain came from layout decisions: whether to disaggregate, how
1. The recorded sessions are replayed with pauses capped at 5 s and generated prompt text, so production traffic will differ in cache reuse, timing and concurrency. For production, give presets your own traffic as the workload.
2. Provider figures are OpenRouter's measurements of its users' requests to each endpoint, not of our workload, and we serve the NVFP4 checkpoint while Baseten's fast endpoints serve FP8.
-3. The cost compares self-hosting with buying the same tokens, not with what providers pay to serve them. It counts only GPU rental and assumes the 56 chips produce 17.54 million output tokens in every hour they are rented, at $4.00 per chip-hour, [SemiAnalysis's retail price](https://inferencex.semianalysis.com/chips/gb200-nvl72) for GB200 NVL72. It leaves out the router node, storage, operations and idle hours.
+3. The comparison sets what the fleet produces per GPU-hour against the price of buying the same tokens, not against what providers pay to serve them. It leaves out what a GPU-hour costs, which depends on whether the GPUs are rented or owned, and assumes every GPU-hour produces 313k output tokens. It also leaves out the router node, storage, operations and idle hours.
4. The preset agent spent its sessions on layout rather than engine settings, source patches or kernels, so more gains are likely.
5. The comparison with SemiAnalysis is approximate. Their run served the GLM-5.2 NVFP4 checkpoint, which has the same architecture but a different quantization recipe. The SGLang builds also differ, we used 64 chips against their 32, and our benchmark window was 929 s against their 3,625 s, so we compare only throughput per chip.
diff --git a/mkdocs/overrides/main.html b/mkdocs/overrides/main.html
index faf1a3e6a..d7a1124c6 100644
--- a/mkdocs/overrides/main.html
+++ b/mkdocs/overrides/main.html
@@ -228,7 +228,7 @@
{% endblock %}
{% block announce %}
-Serve GLM-5.3 Coding Agents Faster and Cheaper on GB200 NVL72
+Serve Fastest Qwen3.8-Flash-Next Coding Agents on 4xH200
{% endblock %}
{# Footer is rendered INSIDE .md-content (above, after the article) — NOT as a full-width sibling —
diff --git a/scripts/docs/hooks.py b/scripts/docs/hooks.py
index ca78a48cf..b3ba68955 100644
--- a/scripts/docs/hooks.py
+++ b/scripts/docs/hooks.py
@@ -11,6 +11,7 @@
from xml.sax.saxutils import escape
import yaml
+from material.plugins.blog.structure import View
from mkdocs.structure.files import File
@@ -245,6 +246,14 @@ def _swagger_error(pre_token: str, post_token: str, message: str) -> str:
return pre_token + escape(f"!! SWAGGER ERROR: {message} !!") + post_token
+def on_page_context(context, page, config, nav):
+ """Hide blog posts with `unlisted: true` from the blog index and category pages."""
+ if isinstance(page, View):
+ # In place: paginated pages share the list. Runs before the blog plugin renders views.
+ page.posts[:] = [post for post in page.posts if not post.meta.get("unlisted")]
+ return context
+
+
def on_config(config):
if os.environ.get(DISABLE_YAML_SCHEMAS_ENV):
log.warning("YAML schema reference generation is disabled")
diff --git a/website/src/components/SiteBanner.tsx b/website/src/components/SiteBanner.tsx
index b5d7dd0b9..b0e935428 100644
--- a/website/src/components/SiteBanner.tsx
+++ b/website/src/components/SiteBanner.tsx
@@ -3,8 +3,8 @@ import { BLOG_URL } from '../routes';
// Top announcement banner, mirroring the one on the MkDocs docs site. It sits above the top
// nav; the two stick to the top together (see .site-header). Update the copy/href here when
// the announcement changes.
-const BANNER_TEXT = 'Serve GLM-5.3 Coding Agents Faster and Cheaper on GB200 NVL72';
-const BANNER_HREF = `${BLOG_URL}/glm53-gb200-nvl72-coding-agents/`;
+const BANNER_TEXT = 'Serve Fastest Qwen3.8-Flash-Next Coding Agents on 4xH200';
+const BANNER_HREF = `${BLOG_URL}/qwen38-flash-next-coding-agents/`;
export function SiteBanner() {
return (
 @@ -18,7 +19,7 @@ This work was done jointly with [Crusoe](https://crusoe.ai), who provided the GB
-On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three fastest GLM-5.3 endpoints on OpenRouter, about 3x lower p50 TTFT, and 2x or more higher output speed at p99, where a coding agent's slowest turns are. Serving the same work ourselves costs $12.77 per million output tokens, against $43–66 when buying it from these endpoints.
+On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three fastest GLM-5.3 endpoints on OpenRouter, about 3x lower p50 TTFT, and 2x or more higher output speed at p99, where a coding agent's slowest turns are. Each GPU-hour of the fleet produces 313k output tokens, which would cost $13.51–20.71 to buy from these endpoints.
=== "tok/s/user p50"
 @@ -32,10 +33,7 @@ On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three
=== "TTFT p99"
 -=== "Cost"
-
 -
-> Output speed follows OpenRouter's definition: output tokens per second from sending the request to the end of the response, TTFT included. The self-hosting cost is 56 chips at [$4.00 per chip-hour](https://inferencex.semianalysis.com/chips/gb200-nvl72) divided by the 17.54 million output tokens the fleet produces per hour. The cost of buying applies each endpoint's list prices, including cache-read prices, to our exact token counts. Provider figures are OpenRouter's for 19–26 October.
+> Output speed follows OpenRouter's definition: output tokens per second from sending the request to the end of the response, TTFT included. A GPU-hour's output is the fleet's 17.54 million output tokens per hour divided by its 56 GPUs. The cost of buying applies each endpoint's list prices, including cache-read prices, to our exact token counts. Provider figures are OpenRouter's for 19–26 October.
## Purpose
@@ -107,7 +105,7 @@ We then raised the agent count for each winner. Aggregated, replayed at normal p
### Self-hosting is economically viable
-Optimized for 48 agents, 14 GB200 nodes match the fastest GLM-5.3 endpoints on p50 output speed and beat them on p50 TTFT and on output speed at p99. Self-hosting costs $12.77 per million output tokens, at least 70% less than the $43–66 it costs to buy the same tokens from these endpoints.
+Optimized for 48 agents, 14 GB200 nodes match the fastest GLM-5.3 endpoints on p50 output speed and beat them on p50 TTFT and on output speed at p99. Self-hosting them costs less than buying the same tokens from these endpoints, even on GB200 NVL72 and without patching the engine or writing kernels.
### Cache fit decides aggregated vs PD
@@ -125,7 +123,7 @@ Almost all of the gain came from layout decisions: whether to disaggregate, how
1. The recorded sessions are replayed with pauses capped at 5 s and generated prompt text, so production traffic will differ in cache reuse, timing and concurrency. For production, give presets your own traffic as the workload.
2. Provider figures are OpenRouter's measurements of its users' requests to each endpoint, not of our workload, and we serve the NVFP4 checkpoint while Baseten's fast endpoints serve FP8.
-3. The cost compares self-hosting with buying the same tokens, not with what providers pay to serve them. It counts only GPU rental and assumes the 56 chips produce 17.54 million output tokens in every hour they are rented, at $4.00 per chip-hour, [SemiAnalysis's retail price](https://inferencex.semianalysis.com/chips/gb200-nvl72) for GB200 NVL72. It leaves out the router node, storage, operations and idle hours.
+3. The comparison sets what the fleet produces per GPU-hour against the price of buying the same tokens, not against what providers pay to serve them. It leaves out what a GPU-hour costs, which depends on whether the GPUs are rented or owned, and assumes every GPU-hour produces 313k output tokens. It also leaves out the router node, storage, operations and idle hours.
4. The preset agent spent its sessions on layout rather than engine settings, source patches or kernels, so more gains are likely.
5. The comparison with SemiAnalysis is approximate. Their run served the GLM-5.2 NVFP4 checkpoint, which has the same architecture but a different quantization recipe. The SGLang builds also differ, we used 64 chips against their 32, and our benchmark window was 929 s against their 3,625 s, so we compare only throughput per chip.
diff --git a/mkdocs/overrides/main.html b/mkdocs/overrides/main.html
index faf1a3e6a..d7a1124c6 100644
--- a/mkdocs/overrides/main.html
+++ b/mkdocs/overrides/main.html
@@ -228,7 +228,7 @@
{% endblock %}
{% block announce %}
-Serve GLM-5.3 Coding Agents Faster and Cheaper on GB200 NVL72
+Serve Fastest Qwen3.8-Flash-Next Coding Agents on 4xH200
{% endblock %}
{# Footer is rendered INSIDE .md-content (above, after the article) — NOT as a full-width sibling —
diff --git a/scripts/docs/hooks.py b/scripts/docs/hooks.py
index ca78a48cf..b3ba68955 100644
--- a/scripts/docs/hooks.py
+++ b/scripts/docs/hooks.py
@@ -11,6 +11,7 @@
from xml.sax.saxutils import escape
import yaml
+from material.plugins.blog.structure import View
from mkdocs.structure.files import File
@@ -245,6 +246,14 @@ def _swagger_error(pre_token: str, post_token: str, message: str) -> str:
return pre_token + escape(f"!! SWAGGER ERROR: {message} !!") + post_token
+def on_page_context(context, page, config, nav):
+ """Hide blog posts with `unlisted: true` from the blog index and category pages."""
+ if isinstance(page, View):
+ # In place: paginated pages share the list. Runs before the blog plugin renders views.
+ page.posts[:] = [post for post in page.posts if not post.meta.get("unlisted")]
+ return context
+
+
def on_config(config):
if os.environ.get(DISABLE_YAML_SCHEMAS_ENV):
log.warning("YAML schema reference generation is disabled")
diff --git a/website/src/components/SiteBanner.tsx b/website/src/components/SiteBanner.tsx
index b5d7dd0b9..b0e935428 100644
--- a/website/src/components/SiteBanner.tsx
+++ b/website/src/components/SiteBanner.tsx
@@ -3,8 +3,8 @@ import { BLOG_URL } from '../routes';
// Top announcement banner, mirroring the one on the MkDocs docs site. It sits above the top
// nav; the two stick to the top together (see .site-header). Update the copy/href here when
// the announcement changes.
-const BANNER_TEXT = 'Serve GLM-5.3 Coding Agents Faster and Cheaper on GB200 NVL72';
-const BANNER_HREF = `${BLOG_URL}/glm53-gb200-nvl72-coding-agents/`;
+const BANNER_TEXT = 'Serve Fastest Qwen3.8-Flash-Next Coding Agents on 4xH200';
+const BANNER_HREF = `${BLOG_URL}/qwen38-flash-next-coding-agents/`;
export function SiteBanner() {
return (