diff --git a/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md b/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md
index ce82c2219..7269bb269 100644
--- a/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md
+++ b/mkdocs/blog/posts/glm53-gb200-nvl72-coding-agents.md
@@ -19,7 +19,7 @@ This work was done jointly with [Crusoe](https://crusoe.ai), who provided the GB
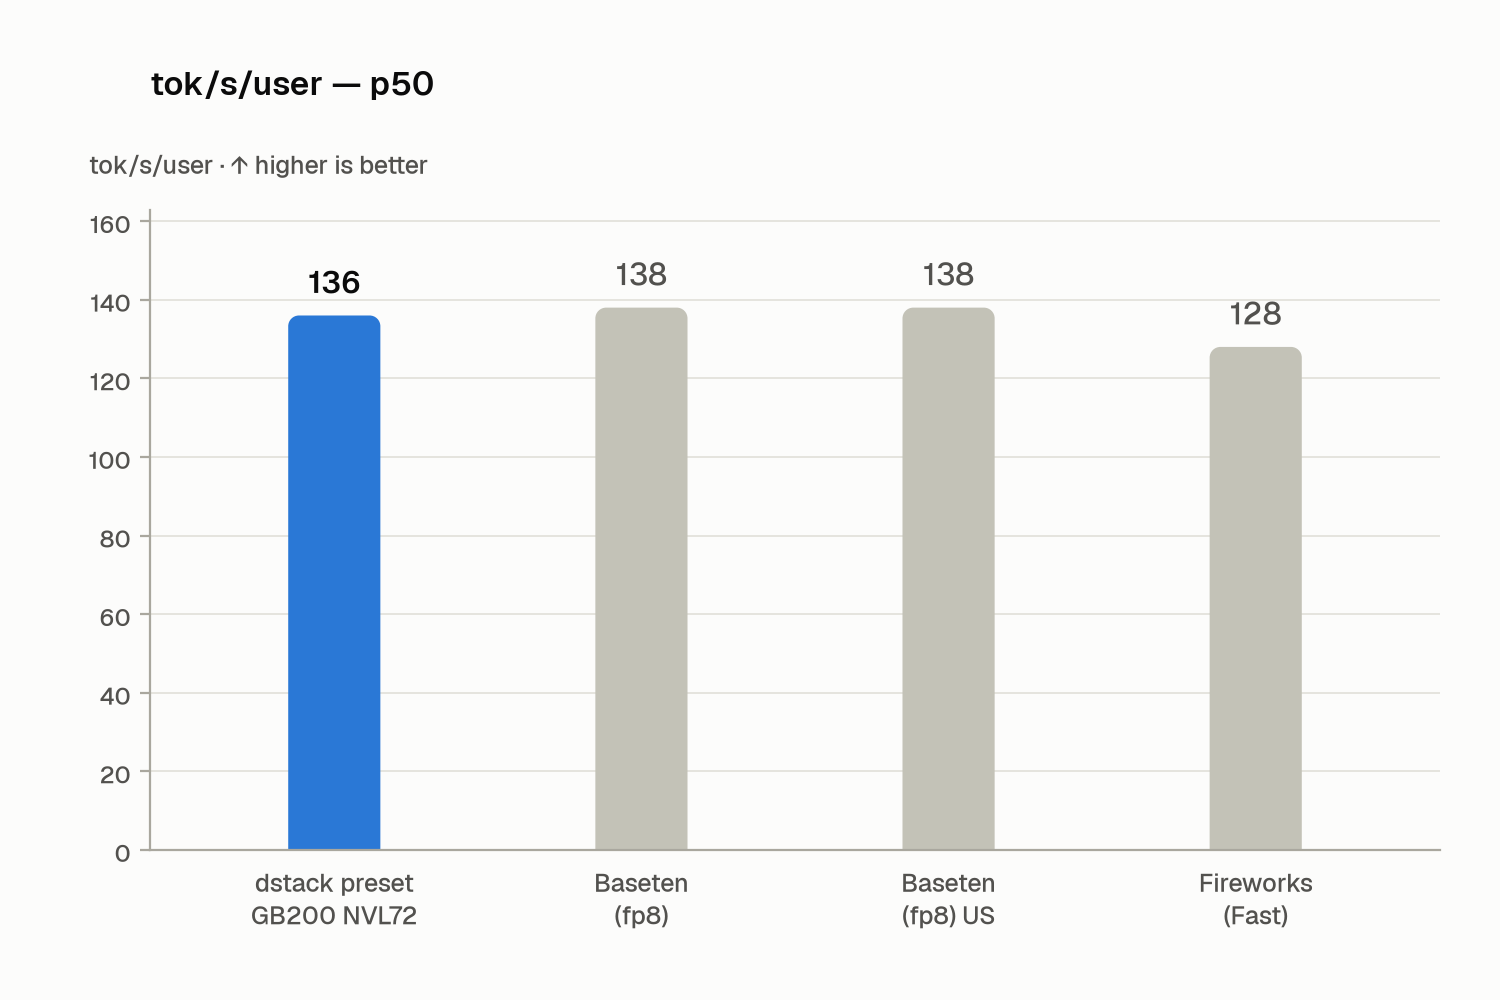
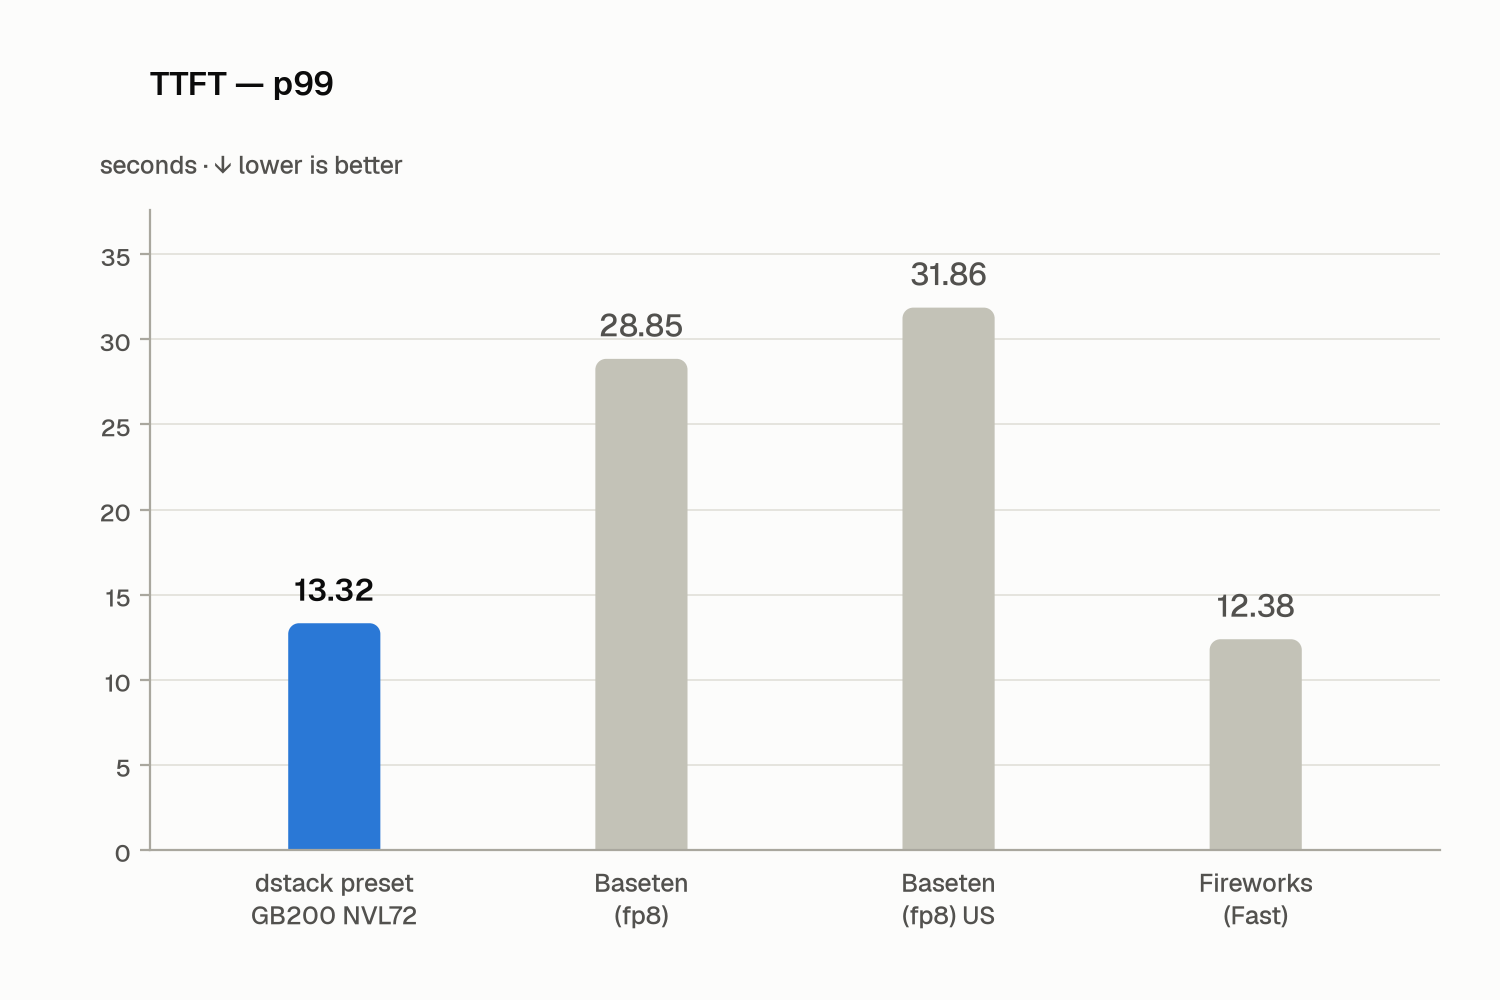
-On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three fastest GLM-5.3 endpoints on OpenRouter, about 3x lower p50 TTFT, and 2x or more higher output speed at p99, where a coding agent's slowest turns are. Serving the same work ourselves costs $12.77 per million output tokens, against $43–66 when buying it from these endpoints.
+On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three fastest GLM-5.3 endpoints on OpenRouter, about 3x lower p50 TTFT, and 2x or more higher output speed at p99, where a coding agent's slowest turns are. Each GPU-hour of the fleet produces 313k output tokens, which would cost $13.51–20.71 to buy from these endpoints.
=== "tok/s/user p50"
 @@ -33,10 +33,7 @@ On 14 GB200 nodes, 48 agents get the same p50 output speed per user as the three
=== "TTFT p99"
 -=== "Cost"
-
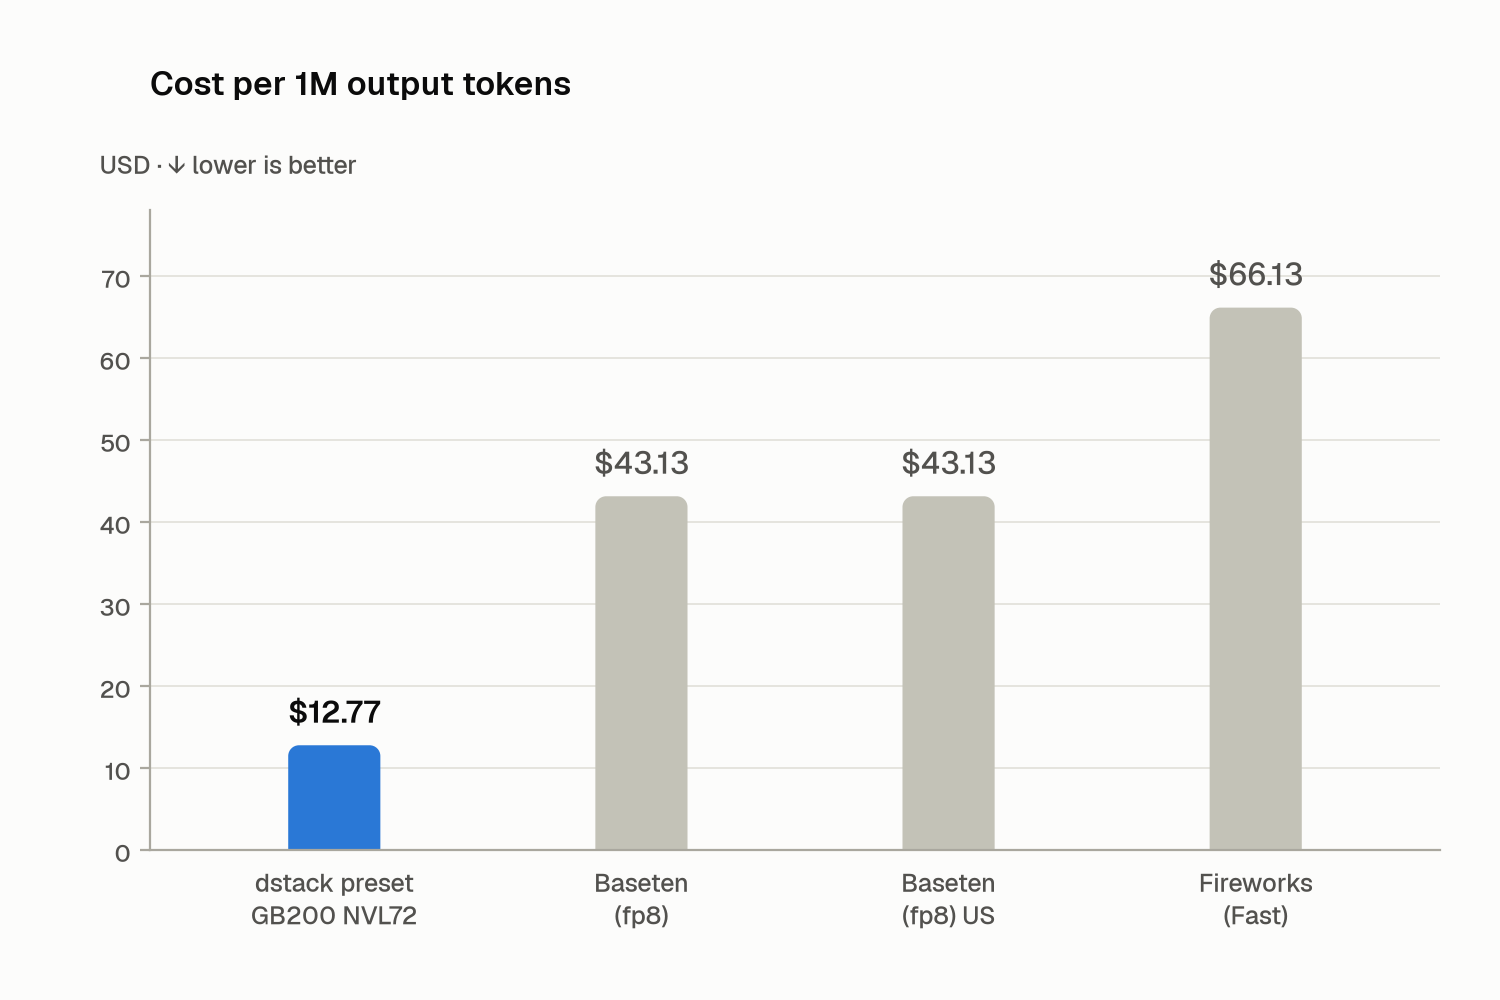 -
-> Output speed follows OpenRouter's definition: output tokens per second from sending the request to the end of the response, TTFT included. The self-hosting cost is 56 chips at [$4.00 per chip-hour](https://inferencex.semianalysis.com/chips/gb200-nvl72) divided by the 17.54 million output tokens the fleet produces per hour. The cost of buying applies each endpoint's list prices, including cache-read prices, to our exact token counts. Provider figures are OpenRouter's for 19–26 October.
+> Output speed follows OpenRouter's definition: output tokens per second from sending the request to the end of the response, TTFT included. A GPU-hour's output is the fleet's 17.54 million output tokens per hour divided by its 56 GPUs. The cost of buying applies each endpoint's list prices, including cache-read prices, to our exact token counts. Provider figures are OpenRouter's for 19–26 October.
## Purpose
@@ -126,7 +123,7 @@ Almost all of the gain came from layout decisions: whether to disaggregate, how
1. The recorded sessions are replayed with pauses capped at 5 s and generated prompt text, so production traffic will differ in cache reuse, timing and concurrency. For production, give presets your own traffic as the workload.
2. Provider figures are OpenRouter's measurements of its users' requests to each endpoint, not of our workload, and we serve the NVFP4 checkpoint while Baseten's fast endpoints serve FP8.
-3. The cost compares self-hosting with buying the same tokens, not with what providers pay to serve them. It counts only GPU rental and assumes the 56 chips produce 17.54 million output tokens in every hour they are rented, at $4.00 per chip-hour, [SemiAnalysis's retail price](https://inferencex.semianalysis.com/chips/gb200-nvl72) for GB200 NVL72. It leaves out the router node, storage, operations and idle hours.
+3. The comparison sets what the fleet produces per GPU-hour against the price of buying the same tokens, not against what providers pay to serve them. It leaves out what a GPU-hour costs, which depends on whether the GPUs are rented or owned, and assumes every GPU-hour produces 313k output tokens. It also leaves out the router node, storage, operations and idle hours.
4. The preset agent spent its sessions on layout rather than engine settings, source patches or kernels, so more gains are likely.
5. The comparison with SemiAnalysis is approximate. Their run served the GLM-5.2 NVFP4 checkpoint, which has the same architecture but a different quantization recipe. The SGLang builds also differ, we used 64 chips against their 32, and our benchmark window was 929 s against their 3,625 s, so we compare only throughput per chip.